AI Model & Product
Prompt caching
Also known as: cached prompts, context caching, prompt cache
Prompt caching is a technique where a model provider stores the processed form of a repeated section of a prompt so it does not have to be recomputed on every request. Later calls that begin with the same content reuse the cached work, which usually lowers cost and reduces time to first token. It applies to the stable parts of a prompt, such as system instructions, retrieved documents or long examples.
What it is
Prompt caching works on the prefix of a request: the opening block of tokens that stays identical across many calls. The provider keeps a representation of that prefix for a limited period and matches incoming requests against it. Cached input tokens are typically billed at a lower rate than fresh input tokens, and cache entries expire after a short window of inactivity.
Why it matters
Retrieval-based and agentic applications often send the same large context repeatedly, so the same tokens get paid for and processed hundreds of times a day. Caching cuts that duplication, which makes long system prompts, extensive brand guidelines and large document contexts economically viable. Faster responses also matter for chat interfaces and for pipelines where several model calls run in sequence.
How it works
Practitioners restructure prompts so everything stable sits at the front and everything variable sits at the end: system instructions, tools and reference documents first, user question last. They keep the prefix byte-identical, avoiding timestamps, session IDs or reordered content that would break the match. Providers differ in whether caching is automatic or requires explicit cache markers, so implementation follows the specific API documentation.
When it applies
It applies whenever the same substantial context is sent repeatedly within a short window, such as support assistants, document question answering, coding agents and batch classification jobs.
Examples
- A support chatbot puts a 4,000 token product manual and tone guide at the top of every request so only the customer message changes.
- A coding agent caches the repository summary and tool definitions across a multi step task, paying full price only for each new instruction.
- A classification job reuses a cached block of 30 labelled examples while feeding in a different item to classify on each call.
How it is measured
- Cache hit rate: share of input tokens served from cache versus computed fresh
- Cost per request before and after caching, split by cached and uncached input tokens
- Time to first token for cache hits compared with cache misses
- Cache invalidation rate caused by prefix changes such as injected variables
Insights on Prompt caching
Related terms in AI Model & Product
- Agents APIAn Agents API is a programming interface for building applications where a model plans, calls tools and completes multi-step tasks rather than returning a single reply. The term is most often used for OpenAI's agent building interfaces, though other vendors offer equivalents. Teams use it to connect models to search, internal data and actions such as booking, updating records or generating reports.
- AI assistantAn AI assistant is a software product that uses a language model to hold a conversation, answer questions and carry out tasks on a user's behalf. It sits on top of one or more underlying models and adds an interface, memory, tools and safety controls. Examples include ChatGPT, Google Gemini, Microsoft Copilot, Claude and voice assistants such as Siri and Alexa.
- AI transcriptionAI transcription is the automatic conversion of spoken audio into written text using speech recognition models. Modern systems often add speaker labels, punctuation, timestamps and language detection, and can feed the output into summarisation or search. It is also called automatic speech recognition or ASR.
- BingBing is Microsooft's web search engine, available at bing.com and integrated into Microsoft Copilot and other Microsoft products. It maintains its own crawler, Bingbot, and its own index, and provides Bing Webmaster Tools for site owners. Its index and APIs have also supplied results to third-party search products and AI assistants.
- ChatGPT VoiceChatGPT Voice is the spoken conversation mode in OpenAI's ChatGPT apps, which lets you talk to the assistant and hear its replies read aloud. Advanced Voice Mode processes speech directly, so exchanges feel closer to a phone call and you can interrupt mid-answer. People use it hands free on mobile, and it is also available on desktop.
- Claude CodeClaude Code is Anthropic's agentic coding tool that works directly with a codebase, reading files, proposing and making edits, and running commands with permission. It runs in the terminal and in supported development environments, driven by natural language instructions rather than manual file by file editing. Marketing and growth teams use it for technical SEO, structured data and data tasks that would otherwise wait for engineering.
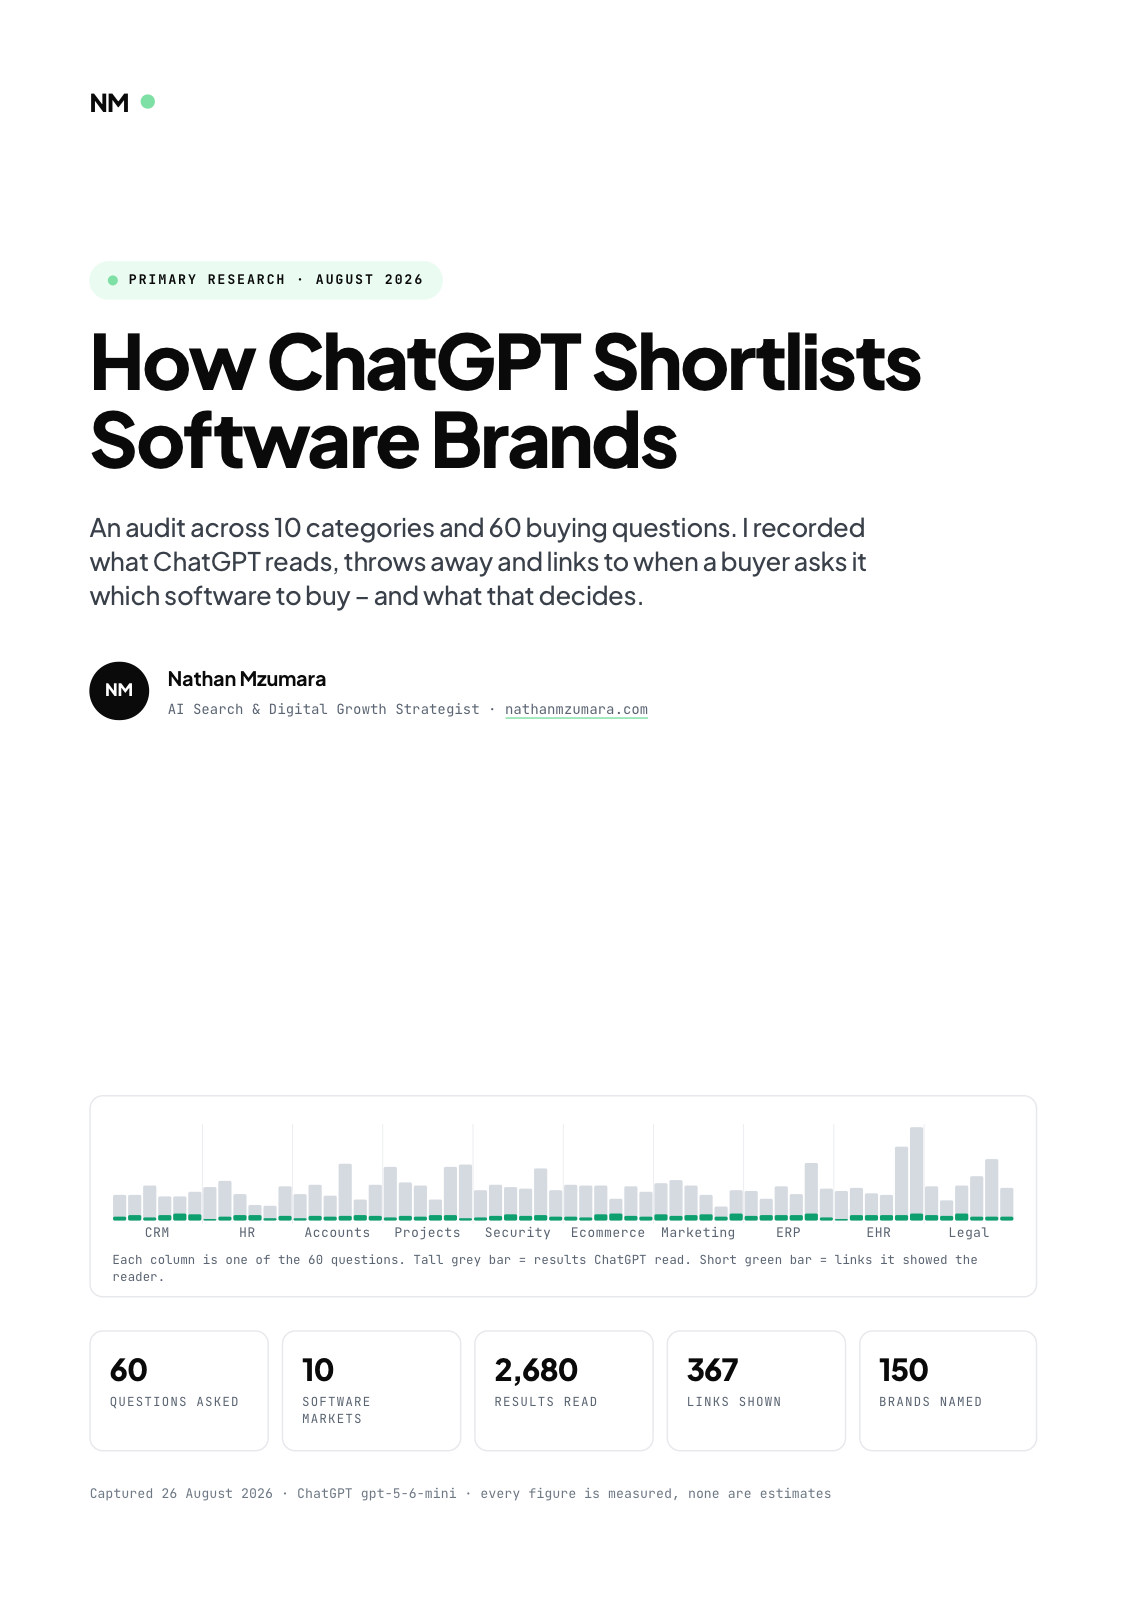
Primary research · August 2026
How ChatGPT Shortlists Software Brands
An audit across 10 categories and 60 buying questions. I recorded what ChatGPT reads, throws away and links to when a buyer asks it which software to buy, and what that decides.
- 60
- Questions asked
- 10
- Software markets
- 2,680
- Results read
- 367
- Links shown
Free download
Get the full report
35 pages · PDF · 536 KB. Enter your details and it downloads straight away.