AI Model & Product
Model routing
Also known as: LLM routing, model router, query routing, router model
Model routing is the practice of sending each request to the most suitable model rather than using one model for everything. A router inspects the incoming query and directs it to a smaller, cheaper model or a larger, more capable one based on rules, classifiers or predicted difficulty. The aim is to hold quality steady while reducing cost and latency.
What it is
A routing layer sits between the application and one or more model providers. It can be a simple rule set based on task type or input length, a trained classifier that scores difficulty, or a cascade that tries a cheap model first and escalates when confidence is low. Some vendors now build routing into their own products, choosing internally between fast and reasoning modes.
Why it matters
Model costs and response times vary widely, and most production traffic is not uniformly hard: a large share of queries can be handled well by smaller models. Routing lets teams spend capability where it changes the answer and save it where it does not. It also reduces lock-in, because traffic can be shifted between providers as prices, limits or quality change.
How it works
Practitioners start by classifying real traffic into task types, then benchmark candidate models on each type to find the cheapest model that meets the quality bar. Routing rules are deployed behind a feature flag, monitored per segment, and adjusted as models are updated. Fallback paths handle provider outages, rate limits and cases where the first model returns low confidence or a refusal.
When it applies
It applies when an application handles a mix of easy and hard requests at enough volume for cost or latency to matter, and when more than one viable model is available.
Examples
- An ecommerce assistant routes stock and delivery questions to a small fast model and product comparison questions to a larger reasoning model.
- A content pipeline uses a cheap model to draft meta descriptions and escalates only pages flagged as high value to a stronger model for review.
- A support tool tries a small model first and re-runs the request on a larger model when the confidence score falls below a set threshold.
How it is measured
- Blended cost per request and cost per resolved task across the routed mix
- Share of traffic handled by each model tier and escalation rate
- Quality scores or human review pass rate per route, compared with a single model baseline
- Median and p95 latency by route, including the cost of escalated retries
Insights on Model routing
Related terms in AI Model & Product
- Agents APIAn Agents API is a programming interface for building applications where a model plans, calls tools and completes multi-step tasks rather than returning a single reply. The term is most often used for OpenAI's agent building interfaces, though other vendors offer equivalents. Teams use it to connect models to search, internal data and actions such as booking, updating records or generating reports.
- AI assistantAn AI assistant is a software product that uses a language model to hold a conversation, answer questions and carry out tasks on a user's behalf. It sits on top of one or more underlying models and adds an interface, memory, tools and safety controls. Examples include ChatGPT, Google Gemini, Microsoft Copilot, Claude and voice assistants such as Siri and Alexa.
- AI transcriptionAI transcription is the automatic conversion of spoken audio into written text using speech recognition models. Modern systems often add speaker labels, punctuation, timestamps and language detection, and can feed the output into summarisation or search. It is also called automatic speech recognition or ASR.
- BingBing is Microsooft's web search engine, available at bing.com and integrated into Microsoft Copilot and other Microsoft products. It maintains its own crawler, Bingbot, and its own index, and provides Bing Webmaster Tools for site owners. Its index and APIs have also supplied results to third-party search products and AI assistants.
- ChatGPT VoiceChatGPT Voice is the spoken conversation mode in OpenAI's ChatGPT apps, which lets you talk to the assistant and hear its replies read aloud. Advanced Voice Mode processes speech directly, so exchanges feel closer to a phone call and you can interrupt mid-answer. People use it hands free on mobile, and it is also available on desktop.
- Claude CodeClaude Code is Anthropic's agentic coding tool that works directly with a codebase, reading files, proposing and making edits, and running commands with permission. It runs in the terminal and in supported development environments, driven by natural language instructions rather than manual file by file editing. Marketing and growth teams use it for technical SEO, structured data and data tasks that would otherwise wait for engineering.
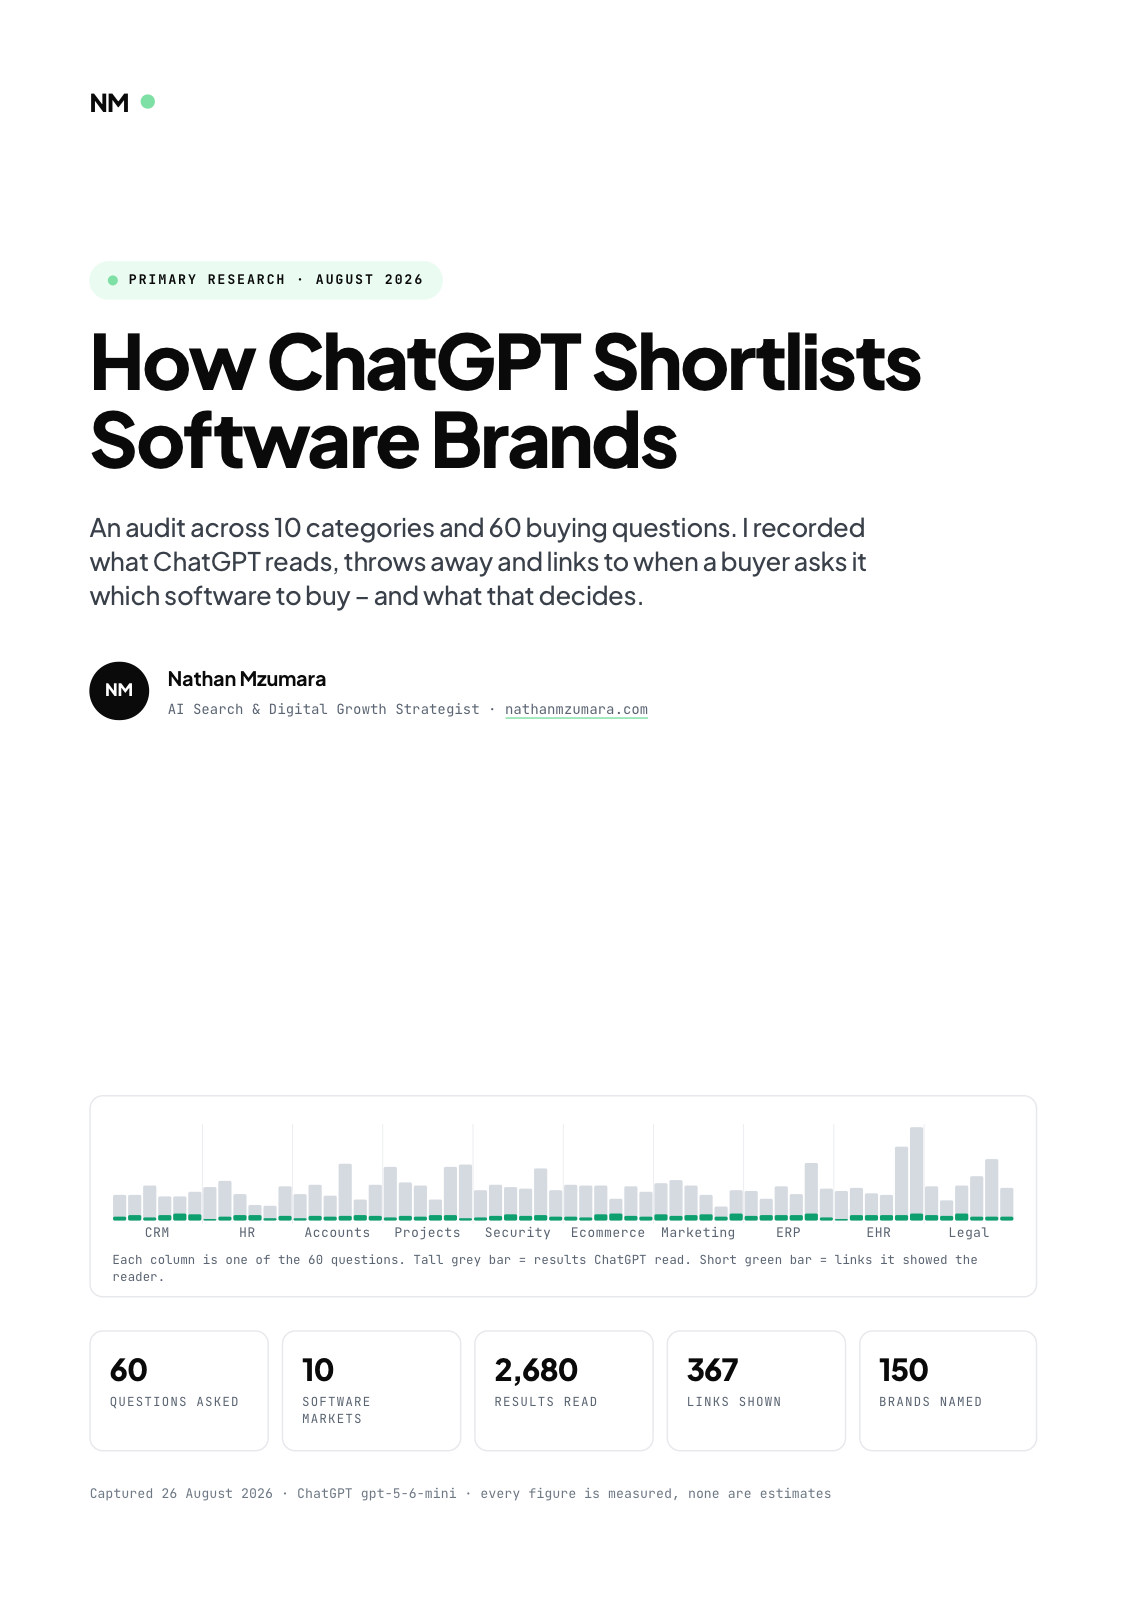
Primary research · August 2026
How ChatGPT Shortlists Software Brands
An audit across 10 categories and 60 buying questions. I recorded what ChatGPT reads, throws away and links to when a buyer asks it which software to buy, and what that decides.
- 60
- Questions asked
- 10
- Software markets
- 2,680
- Results read
- 367
- Links shown
Free download
Get the full report
35 pages · PDF · 536 KB. Enter your details and it downloads straight away.