AI Model & Product
HealthBench
Also known as: OpenAI HealthBench
HealthBench is an open benchmark published by OpenAI for evaluating how large language models behave in realistic health conversations. It scores model responses against rubrics written by practising physicians rather than relying on multiple choice medical exam questions. It is used to compare models on safety, completeness and appropriate caution in health contexts.
What it is
HealthBench consists of realistic, often multi-turn conversations between a user and a model, covering consumer health questions, clinical scenarios and emergency situations across a range of languages and settings. Each conversation has a rubric of specific criteria written by physicians, listing what a good answer should include and what it should avoid. Scoring is done by a model grader that checks responses against those criteria.
Why it matters
Health is a high stakes category where generic quality scores say little about real safety, so benchmarks that reflect actual conversations matter to anyone publishing or relying on health content. For marketers and product teams in health, it is a useful reference point when assessing which models to build on and what behaviour to expect from AI assistants answering questions about your category. It also signals the direction of travel: evaluation is moving from exam style tests towards rubric based judgement of real interactions.
How it works
Researchers and teams run models against the dataset and score the outputs against the physician rubrics, producing results by theme such as emergency referrals, hedging under uncertainty, seeking missing context and communicating clearly. The benchmark is released openly so third parties can reproduce results or use it in their own evaluation stacks. Practitioners typically use it as one input alongside internal evaluations against their own clinical guidance.
When it applies
It applies when you are choosing or evaluating a model for health related use, or when you need evidence about how assistants handle health questions in your category. It is less relevant outside health, though its rubric based method is often borrowed for other high stakes domains.
Examples
- A digital health provider benchmarks two candidate models on HealthBench before selecting one for a symptom guidance feature.
- A content team reviews HealthBench themes such as seeking missing context and mirrors them in its own editorial checklist for health articles.
- An internal evaluation harness reuses the physician rubric format to score model answers against a company's own clinical review standards.
How it is measured
- Overall HealthBench score and score by theme or axis
- Performance on emergency and safety critical scenarios specifically
- Agreement between the model grader and human clinical reviewers on your own test set
- Change in scores across model versions when you upgrade the underlying model
Insights on HealthBench
Related terms in AI Model & Product
- Agents APIAn Agents API is a programming interface for building applications where a model plans, calls tools and completes multi-step tasks rather than returning a single reply. The term is most often used for OpenAI's agent building interfaces, though other vendors offer equivalents. Teams use it to connect models to search, internal data and actions such as booking, updating records or generating reports.
- AI assistantAn AI assistant is a software product that uses a language model to hold a conversation, answer questions and carry out tasks on a user's behalf. It sits on top of one or more underlying models and adds an interface, memory, tools and safety controls. Examples include ChatGPT, Google Gemini, Microsoft Copilot, Claude and voice assistants such as Siri and Alexa.
- AI transcriptionAI transcription is the automatic conversion of spoken audio into written text using speech recognition models. Modern systems often add speaker labels, punctuation, timestamps and language detection, and can feed the output into summarisation or search. It is also called automatic speech recognition or ASR.
- BingBing is Microsooft's web search engine, available at bing.com and integrated into Microsoft Copilot and other Microsoft products. It maintains its own crawler, Bingbot, and its own index, and provides Bing Webmaster Tools for site owners. Its index and APIs have also supplied results to third-party search products and AI assistants.
- ChatGPT VoiceChatGPT Voice is the spoken conversation mode in OpenAI's ChatGPT apps, which lets you talk to the assistant and hear its replies read aloud. Advanced Voice Mode processes speech directly, so exchanges feel closer to a phone call and you can interrupt mid-answer. People use it hands free on mobile, and it is also available on desktop.
- Claude CodeClaude Code is Anthropic's agentic coding tool that works directly with a codebase, reading files, proposing and making edits, and running commands with permission. It runs in the terminal and in supported development environments, driven by natural language instructions rather than manual file by file editing. Marketing and growth teams use it for technical SEO, structured data and data tasks that would otherwise wait for engineering.
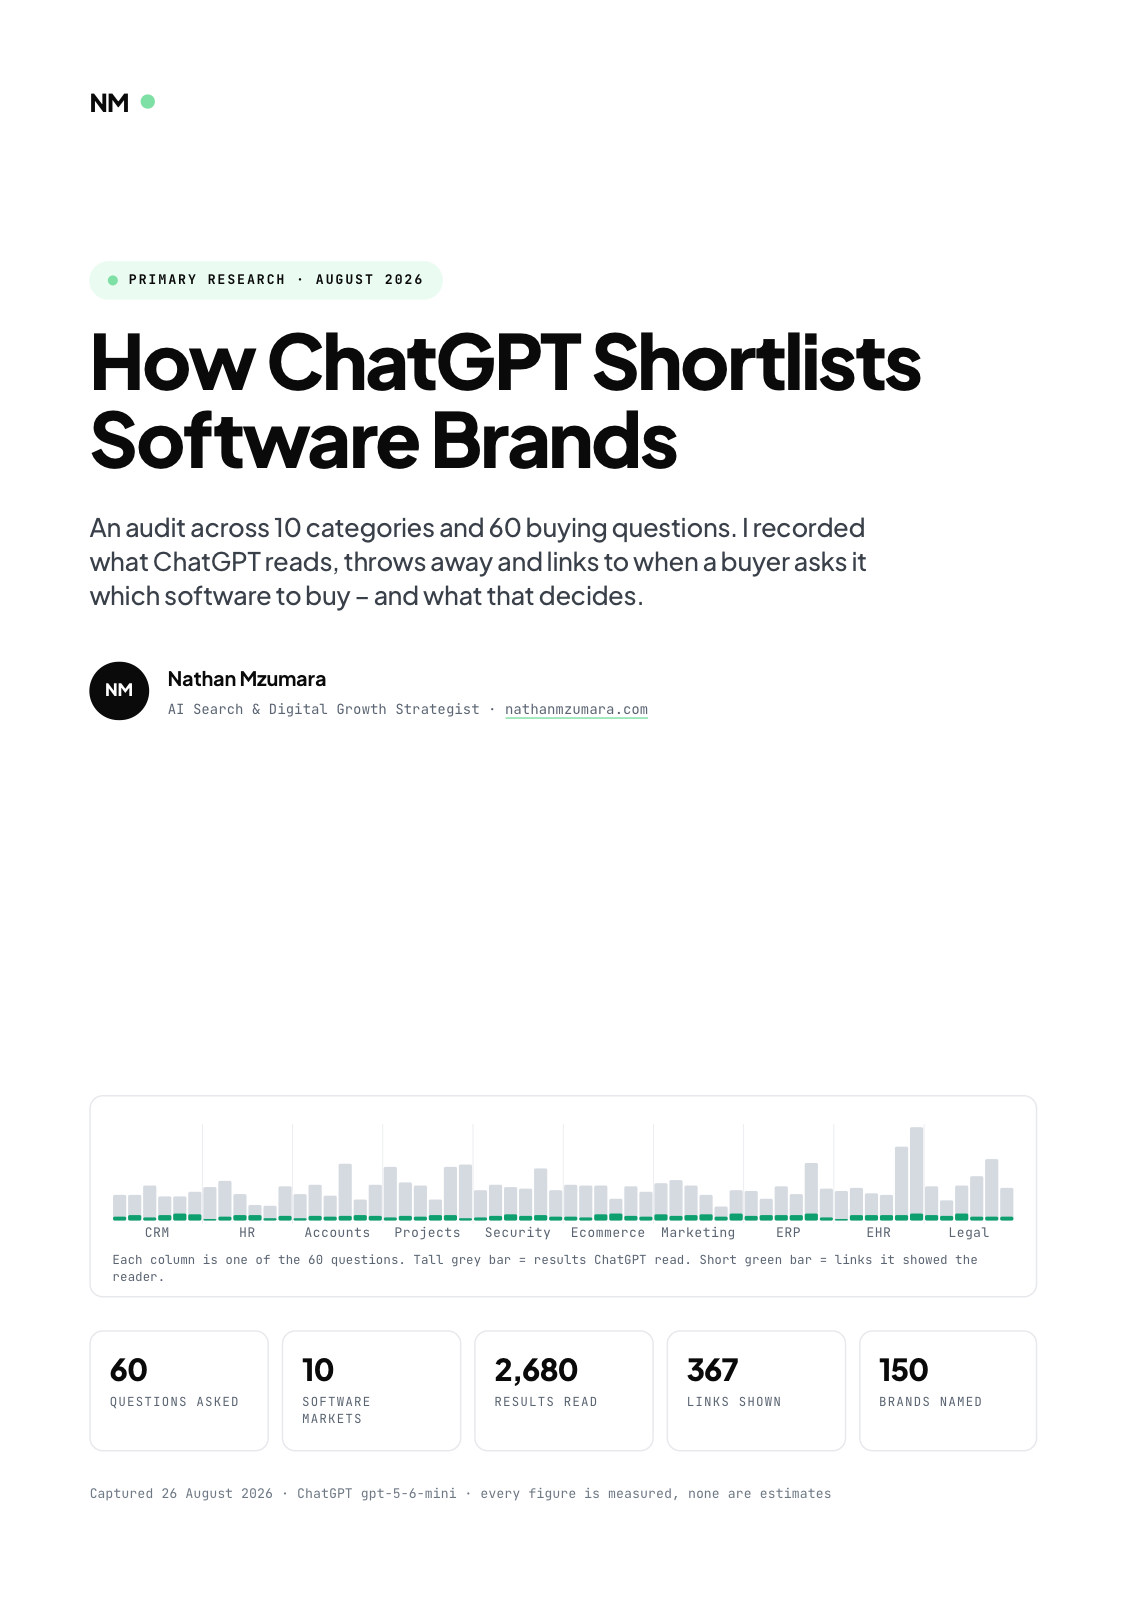
Primary research · August 2026
How ChatGPT Shortlists Software Brands
An audit across 10 categories and 60 buying questions. I recorded what ChatGPT reads, throws away and links to when a buyer asks it which software to buy, and what that decides.
- 60
- Questions asked
- 10
- Software markets
- 2,680
- Results read
- 367
- Links shown
Free download
Get the full report
35 pages · PDF · 536 KB. Enter your details and it downloads straight away.