Enterprise AI
LLM pricing
Also known as: token pricing, model pricing
LLM pricing is how providers charge for access to large language models, most commonly per token of input and output, with separate rates for each model. Subscription tiers, per-seat plans and discounts for cached or batched requests are also common. Understanding it lets teams estimate the running cost of an AI feature before they ship it.
What it is
Token pricing splits usage into what you send the model, the input or prompt, and what it returns, the output or completion. Output tokens usually cost more than input tokens, and more capable models cost more than smaller or distilled ones. Alongside API pricing, most vendors sell consumer and business subscriptions that bundle usage into a monthly fee.
Why it matters
Cost per interaction decides which AI features are viable at scale, so pricing shapes product design as much as model quality does. Long prompts, large retrieved contexts and verbose outputs can multiply spend quickly once traffic grows. For marketing teams, it also governs how much automated content research, classification or prompt monitoring you can afford to run.
How it works
Teams estimate token counts for a typical request, multiply by expected volume, then test cheaper models on the same task to see where quality drops. Common levers include trimming system prompts, reusing cached context, capping output length, batching non-urgent jobs and routing simple requests to a smaller model. Usage dashboards and per-feature tagging keep spend attributable.
When it applies
It applies whenever you build on a model API, buy assistant seats for a team, or budget for recurring AI workloads such as content generation, support triage or visibility tracking.
Examples
- A support team compares the cost per resolved ticket on a large model against a smaller one before rolling out an AI first responder
- A marketing team runs weekly brand visibility prompts in batch mode overnight to reduce API spend
- A product team caches a long system prompt so repeated calls are charged at the cheaper cached input rate
How it is measured
- Cost per request and cost per completed task
- Average input and output tokens per interaction
- Monthly model spend against budget, split by feature
- Spend per resolved outcome, such as a booked demo or closed ticket
Insights on LLM pricing
Related terms in Enterprise AI
- AI agentsAI agents are software systems that use a language model to plan and carry out multi-step tasks, rather than simply returning a block of text. They can call tools, query APIs, browse websites and write to other systems in pursuit of a goal, with varying degrees of human oversight. The term covers everything from a scripted assistant that books a meeting to a research agent that gathers sources and drafts a report.
- AI chipsAI chips are processors designed or optimised to run machine learning workloads, especially the large matrix operations behind training and inference. The category covers GPUs, tensor and neural processing units, and custom ASICs, usually paired with high-bandwidth memory and fast interconnects. They are also called AI accelerators or AI semiconductors.
- AI drug discoveryAI drug discovery is the use of machine learning and computational models to support the early stages of finding and refining new medicines. Models are applied to tasks such as predicting protein structures, identifying candidate molecules, prioritising targets and estimating properties like toxicity or binding affinity. The aim is to narrow a very large search space before expensive laboratory and clinical work begins.
- AI infrastructureAI infrastructure is the stack of hardware, networking, storage and software needed to train, fine-tune and serve AI models at scale. It spans accelerators such as GPUs, the data centres and power that house them, and the orchestration and serving layers that turn raw compute into working model endpoints. For most marketing teams it is a cost and capacity constraint they consume through APIs rather than something they build.
- AI procurementAI procurement is the process of evaluating, buying and contracting artificial intelligence tools and services, from assistants and content platforms to models accessed through an application programming interface. It covers commercial terms alongside security, data protection, accuracy and integration questions that do not arise with ordinary software. Most organisations run it as a structured review with pilots, stakeholder sign off and defined exit conditions.
- AI securityAI security is the practice of protecting AI systems, their data and the applications built on them from misuse, manipulation and leakage. It covers threats such as prompt injection, data exfiltration through model outputs, unsafe tool use by agents and compromised supply chains. It also covers the controls that keep AI features safe once they are live.
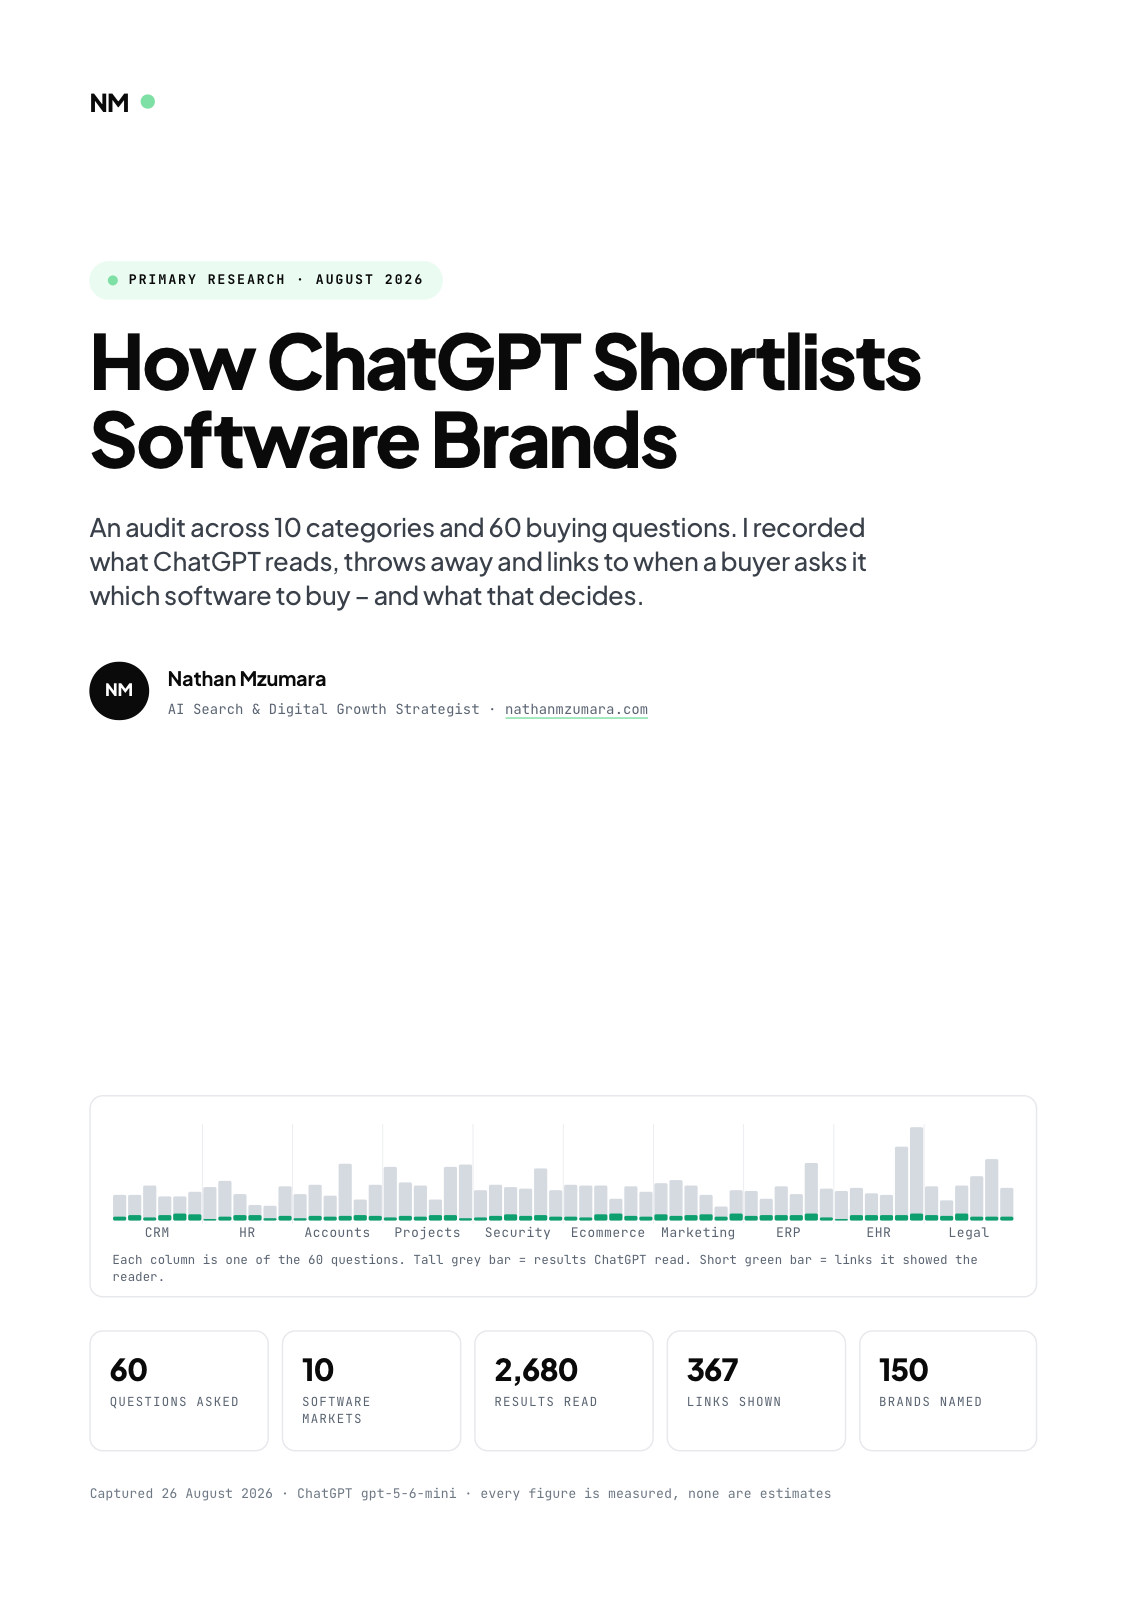
Primary research · August 2026
How ChatGPT Shortlists Software Brands
An audit across 10 categories and 60 buying questions. I recorded what ChatGPT reads, throws away and links to when a buyer asks it which software to buy, and what that decides.
- 60
- Questions asked
- 10
- Software markets
- 2,680
- Results read
- 367
- Links shown
Free download
Get the full report
35 pages · PDF · 536 KB. Enter your details and it downloads straight away.