Enterprise AI
AI chips
Also known as: AI accelerators, AI semiconductors, GPUs for AI
AI chips are processors designed or optimised to run machine learning workloads, especially the large matrix operations behind training and inference. The category covers GPUs, tensor and neural processing units, and custom ASICs, usually paired with high-bandwidth memory and fast interconnects. They are also called AI accelerators or AI semiconductors.
What it is
An AI chip trades general-purpose flexibility for throughput on a narrow set of operations, mainly dense matrix multiplication at low numerical precision. Performance depends as much on memory bandwidth, on-chip memory and interconnect speed as on raw compute, because large models are frequently limited by how fast weights and activations can be moved. Different parts are tuned for different jobs: training accelerators favour bandwidth and cluster scaling, while inference parts often optimise for cost, latency and power per request.
Why it matters
Chip supply, cost and efficiency set the economics of every AI product, which shapes how much inference a vendor can give away free and therefore how AI answer surfaces behave. For marketers, this filters down into token pricing, rate limits and model choice for retrieval and generation pipelines, all of which affect what it costs to publish or to run visibility testing at scale. It is also a heavily searched topic, so accurate explanation of the category is a credibility marker for technology publishers.
How it works
Teams choose accelerators by benchmarking their actual workload rather than by peak specification, measuring throughput and latency at a target batch size and precision. Practitioners compare tokens per second, memory capacity for the model they want to serve, cost per million tokens on hosted endpoints, and power draw where energy or cooling is constrained. Many organisations avoid buying hardware at all and instead select cloud instance types or managed model endpoints, treating chip choice as a pricing and latency decision.
When it applies
It applies when specifying or hosting your own models, choosing cloud instances for retrieval and embedding workloads, or budgeting for large-scale generation and testing. It also applies whenever you publish content that explains AI infrastructure to a technical or executive audience.
Examples
- A data team benchmarks an open-weight model on two GPU instance types and finds memory capacity, not compute, decides how many concurrent users it can serve.
- A SaaS company moves batch embedding of its documentation to a cheaper inference-focused instance and keeps interactive chat on a low-latency one.
- A publisher writes a plain-English explainer of the difference between GPUs, TPUs and custom ASICs for a non-technical executive audience.
How it is measured
- Throughput in tokens per second per accelerator at your target latency
- Cost per million input and output tokens for the workload you actually run
- Accelerator utilisation and queue wait time during peak hours
- Energy or power draw per thousand requests where efficiency is reported
Insights on AI chips
Related terms in Enterprise AI
- AI agentsAI agents are software systems that use a language model to plan and carry out multi-step tasks, rather than simply returning a block of text. They can call tools, query APIs, browse websites and write to other systems in pursuit of a goal, with varying degrees of human oversight. The term covers everything from a scripted assistant that books a meeting to a research agent that gathers sources and drafts a report.
- AI drug discoveryAI drug discovery is the use of machine learning and computational models to support the early stages of finding and refining new medicines. Models are applied to tasks such as predicting protein structures, identifying candidate molecules, prioritising targets and estimating properties like toxicity or binding affinity. The aim is to narrow a very large search space before expensive laboratory and clinical work begins.
- AI infrastructureAI infrastructure is the stack of hardware, networking, storage and software needed to train, fine-tune and serve AI models at scale. It spans accelerators such as GPUs, the data centres and power that house them, and the orchestration and serving layers that turn raw compute into working model endpoints. For most marketing teams it is a cost and capacity constraint they consume through APIs rather than something they build.
- AI procurementAI procurement is the process of evaluating, buying and contracting artificial intelligence tools and services, from assistants and content platforms to models accessed through an application programming interface. It covers commercial terms alongside security, data protection, accuracy and integration questions that do not arise with ordinary software. Most organisations run it as a structured review with pilots, stakeholder sign off and defined exit conditions.
- AI securityAI security is the practice of protecting AI systems, their data and the applications built on them from misuse, manipulation and leakage. It covers threats such as prompt injection, data exfiltration through model outputs, unsafe tool use by agents and compromised supply chains. It also covers the controls that keep AI features safe once they are live.
- AI triageAI triage is the use of machine learning or language models to sort, prioritise and route incoming cases so that the most urgent or most suitable ones reach the right person first. It is used in clinical settings for symptom assessment and in service operations for tickets, leads and enquiries. The system classifies and ranks, while a human usually makes the final decision.
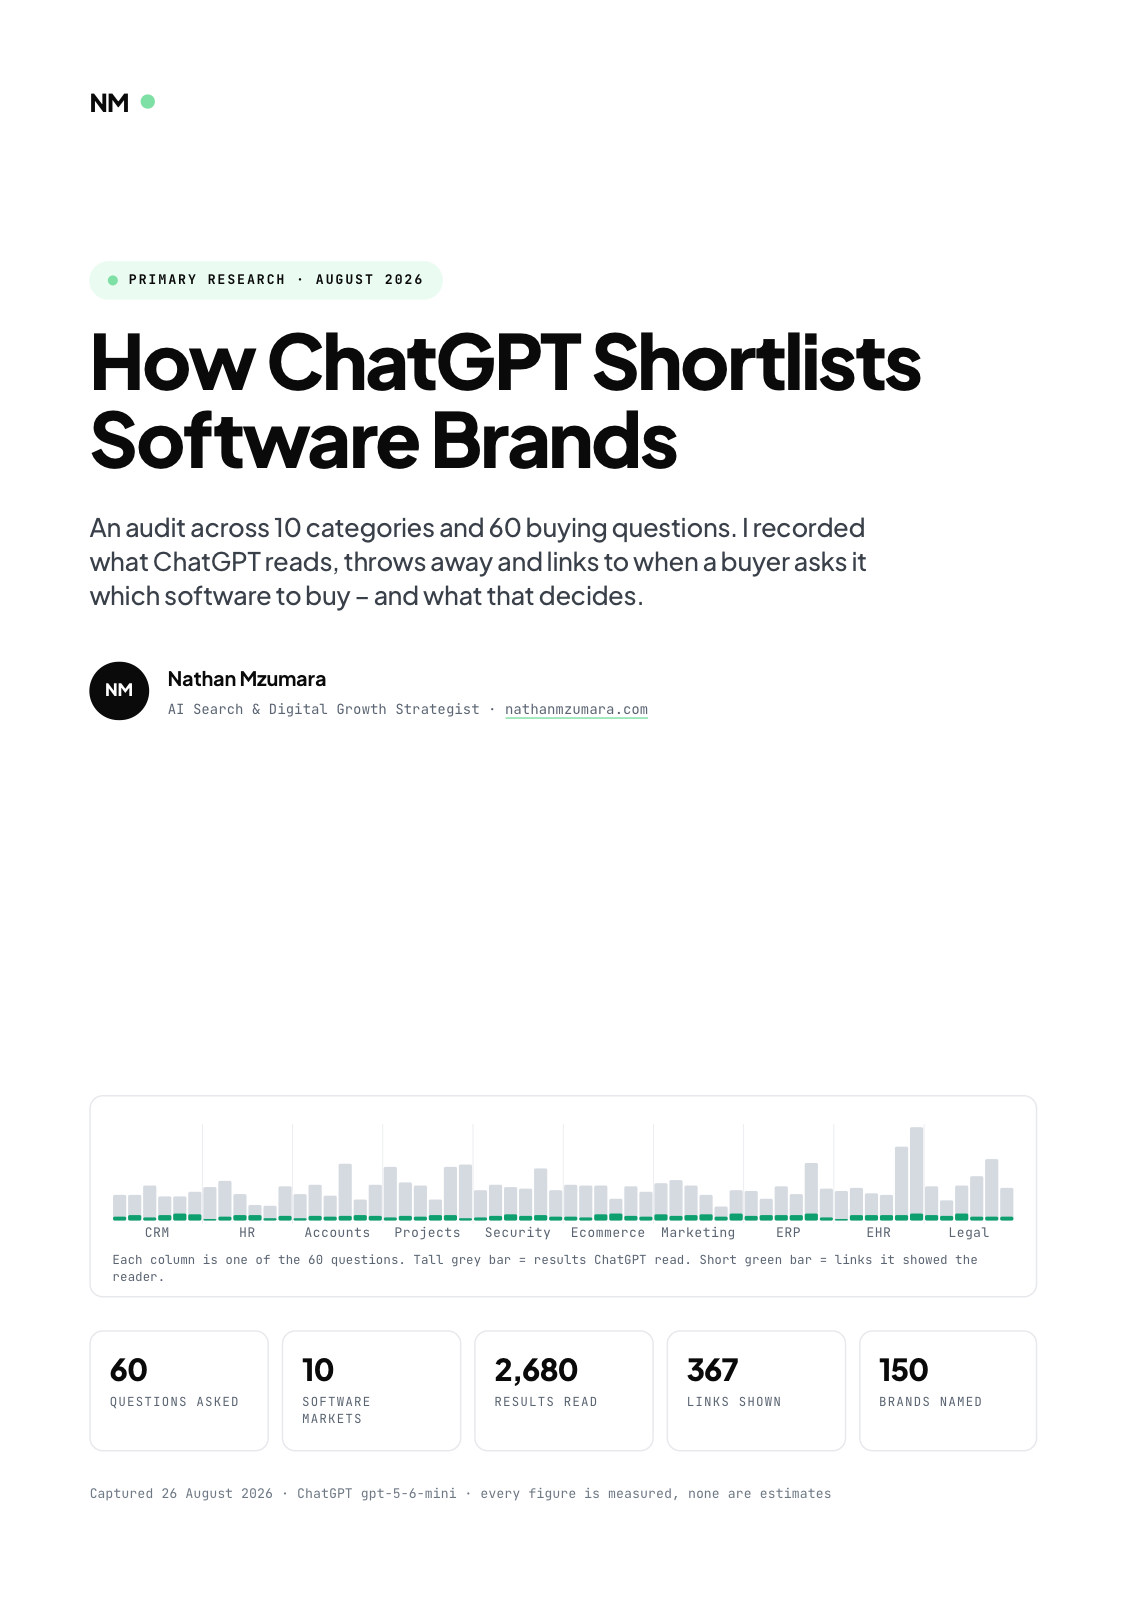
Primary research · August 2026
How ChatGPT Shortlists Software Brands
An audit across 10 categories and 60 buying questions. I recorded what ChatGPT reads, throws away and links to when a buyer asks it which software to buy, and what that decides.
- 60
- Questions asked
- 10
- Software markets
- 2,680
- Results read
- 367
- Links shown
Free download
Get the full report
35 pages · PDF · 536 KB. Enter your details and it downloads straight away.