Enterprise AI
Custom silicon
Also known as: custom chips, in-house silicon, ASICs
Custom silicon is computer hardware designed by a company for its own specific workloads rather than bought as a general purpose part. In AI, it usually means accelerator chips built to train or run models efficiently, often as application specific integrated circuits (ASICs). Large cloud and model providers use it to cut cost per unit of compute and reduce dependence on third party suppliers.
What it is
Custom silicon covers chips and supporting hardware that an organisation specifies and commissions instead of using off the shelf processors. In AI it typically refers to accelerators for training and inference, alongside custom CPUs, networking and memory design. Examples include Google's TPUs, AWS Trainium and Inferentia, Microsoft's Maia and Meta's MTIA family.
Why it matters
AI answer engines and assistants run on enormous amounts of inference, so the cost and speed of that compute shape what products get built and how they are priced. Cheaper, faster inference makes richer retrieval, longer context and more frequent crawling economically viable, which in turn affects how much content an assistant can read before answering. For marketers it is background infrastructure, but it helps explain why assistant capabilities and API prices change as quickly as they do.
How it works
Providers profile their dominant workloads, then design chips tuned to those maths operations and memory patterns, usually working with a fabrication partner and a specialist design team. The silicon is paired with a software stack of compilers and runtimes so existing models can be mapped onto it, and it is deployed inside the provider's own data centres rather than sold widely. Buyers encounter it indirectly, through instance types, model endpoints or pricing tiers that run on particular hardware.
When it applies
It applies when you are evaluating AI infrastructure costs, choosing a cloud or inference provider, or trying to explain why model pricing, latency and availability shift over time.
Examples
- A cloud provider offers a cheaper inference instance type backed by its own accelerator rather than general purpose GPUs.
- A model developer signs a multi year deal to train on a partner's in-house chips to secure capacity.
- An enterprise team benchmarks the same open weight model on GPU and custom accelerator endpoints before committing to one.
How it is measured
- Cost per million tokens or per training hour on each hardware option
- Throughput and latency at a fixed batch size and context length
- Performance per watt or per rack for capacity planning
- Share of workloads successfully migrated to the target hardware without accuracy loss
Insights on Custom silicon
Related terms in Enterprise AI
- AI agentsAI agents are software systems that use a language model to plan and carry out multi-step tasks, rather than simply returning a block of text. They can call tools, query APIs, browse websites and write to other systems in pursuit of a goal, with varying degrees of human oversight. The term covers everything from a scripted assistant that books a meeting to a research agent that gathers sources and drafts a report.
- AI chipsAI chips are processors designed or optimised to run machine learning workloads, especially the large matrix operations behind training and inference. The category covers GPUs, tensor and neural processing units, and custom ASICs, usually paired with high-bandwidth memory and fast interconnects. They are also called AI accelerators or AI semiconductors.
- AI drug discoveryAI drug discovery is the use of machine learning and computational models to support the early stages of finding and refining new medicines. Models are applied to tasks such as predicting protein structures, identifying candidate molecules, prioritising targets and estimating properties like toxicity or binding affinity. The aim is to narrow a very large search space before expensive laboratory and clinical work begins.
- AI infrastructureAI infrastructure is the stack of hardware, networking, storage and software needed to train, fine-tune and serve AI models at scale. It spans accelerators such as GPUs, the data centres and power that house them, and the orchestration and serving layers that turn raw compute into working model endpoints. For most marketing teams it is a cost and capacity constraint they consume through APIs rather than something they build.
- AI procurementAI procurement is the process of evaluating, buying and contracting artificial intelligence tools and services, from assistants and content platforms to models accessed through an application programming interface. It covers commercial terms alongside security, data protection, accuracy and integration questions that do not arise with ordinary software. Most organisations run it as a structured review with pilots, stakeholder sign off and defined exit conditions.
- AI securityAI security is the practice of protecting AI systems, their data and the applications built on them from misuse, manipulation and leakage. It covers threats such as prompt injection, data exfiltration through model outputs, unsafe tool use by agents and compromised supply chains. It also covers the controls that keep AI features safe once they are live.
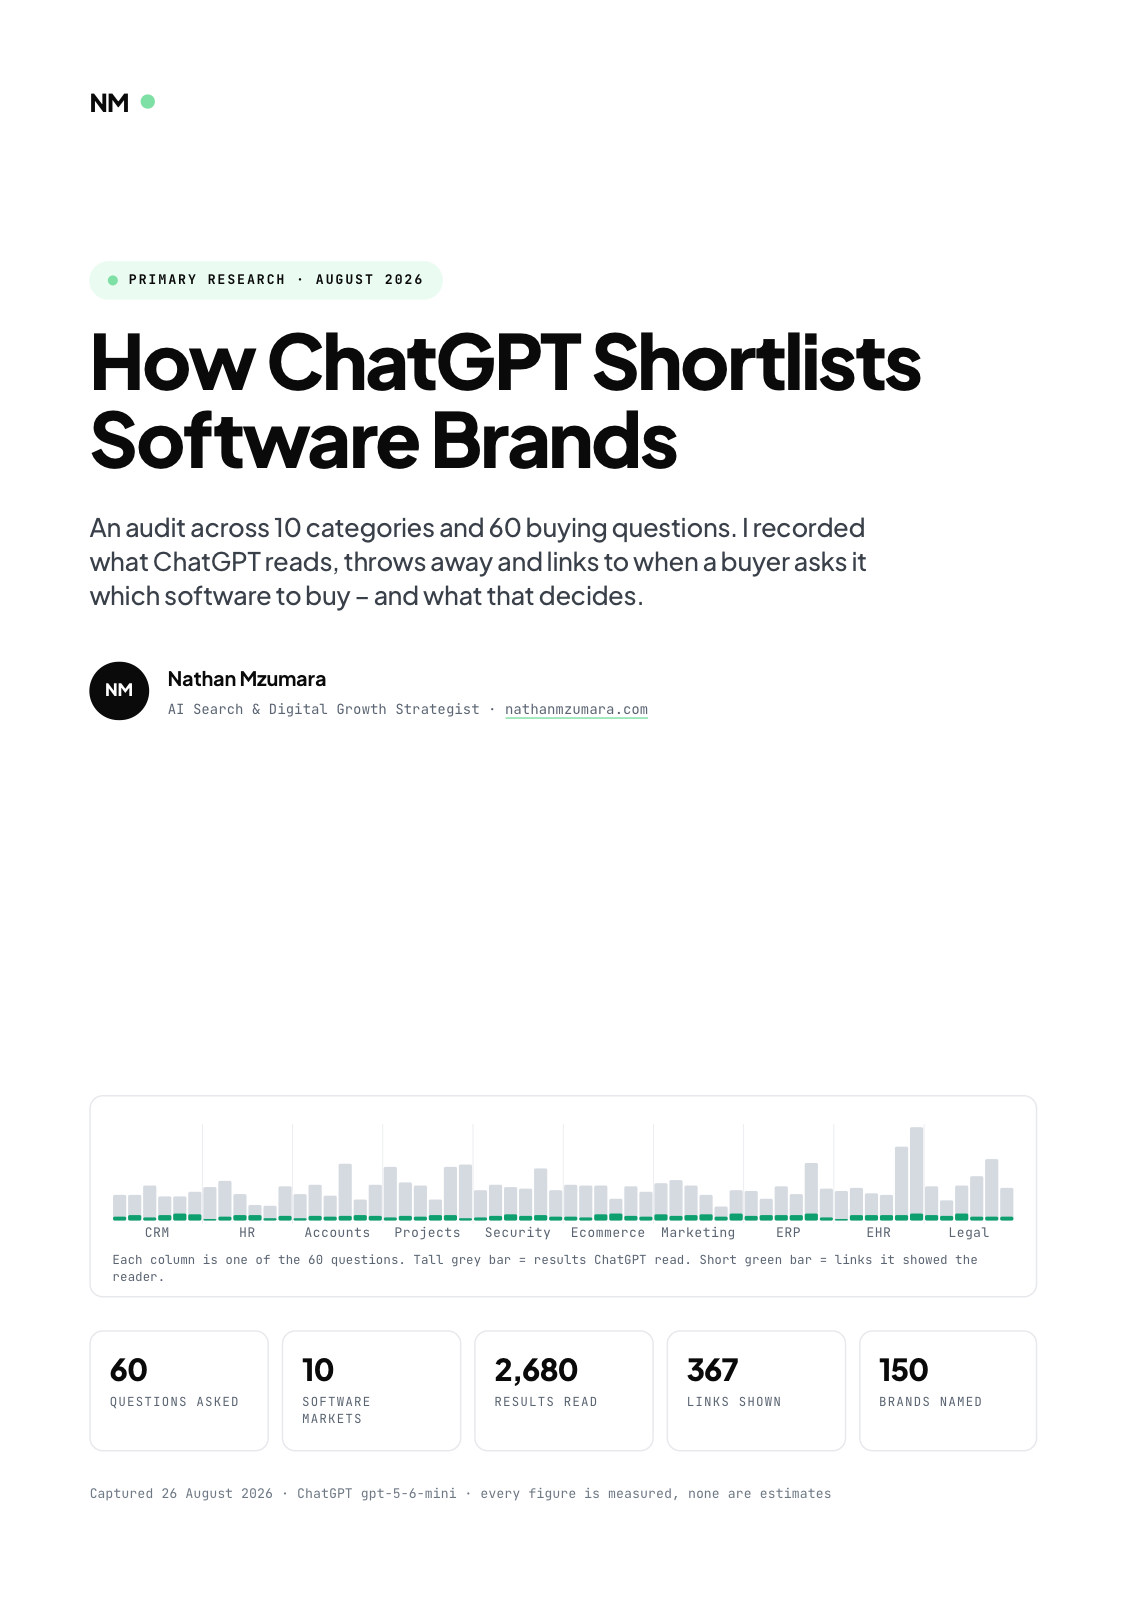
Primary research · August 2026
How ChatGPT Shortlists Software Brands
An audit across 10 categories and 60 buying questions. I recorded what ChatGPT reads, throws away and links to when a buyer asks it which software to buy, and what that decides.
- 60
- Questions asked
- 10
- Software markets
- 2,680
- Results read
- 367
- Links shown
Free download
Get the full report
35 pages · PDF · 536 KB. Enter your details and it downloads straight away.