Enterprise AI
AIOps
Also known as: AI Ops, AI operations, artificial intelligence for IT operations
AIOps is the use of machine learning and analytics on IT operations data, such as logs, metrics, traces and alerts, to detect problems, group related signals and speed up diagnosis. It aims to cut alert noise, surface likely causes and trigger automated responses instead of relying on manual triage. The term covers both dedicated platforms and AI features built into existing monitoring tools.
What it is
AIOps sits on top of observability data, taking the high volume streams that monitoring systems produce and applying anomaly detection, correlation and pattern recognition to them. Typical outputs are a small number of grouped incidents with a probable cause, rather than thousands of individual alerts. Many platforms add runbook automation so common fixes can run without a human step.
Why it matters
Availability and speed are the base layer of discovery, since an outage or a slow origin stops crawlers, breaks feeds and loses sales for as long as it lasts. Faster detection and resolution shortens that window and protects indexing, ad delivery and revenue during peaks. It also frees engineering time that would otherwise go on repetitive alert handling.
How it works
Teams centralise logs, metrics and traces, set baselines so the system can learn normal behaviour, then let the platform flag deviations and cluster related alerts into single incidents. Findings are routed to on call staff with context, and recurring fixes are automated through scripts or runbooks. Practitioners review post incident data to retire noisy alerts and improve the models and thresholds over time.
When it applies
It applies to organisations running enough systems that alert volume and incident complexity exceed what manual monitoring handles well. It is most valuable for high traffic sites, ecommerce peaks and any estate where several teams own interdependent services.
Examples
- A retailer's platform groups 400 alerts from a failing checkout dependency into one incident with a suspected cause
- An anomaly detector flags a sudden rise in 500 errors on product pages before customer complaints arrive
- A runbook automatically restarts a stuck feed service and notifies the team, keeping a product feed submission on schedule
How it is measured
- Mean time to detect and mean time to resolve incidents
- Alert volume and ratio of alerts to confirmed incidents
- Uptime for revenue and crawl critical pages
- Share of incidents resolved by automated remediation without escalation
Insights on AIOps
Related terms in Enterprise AI
- AI agentsAI agents are software systems that use a language model to plan and carry out multi-step tasks, rather than simply returning a block of text. They can call tools, query APIs, browse websites and write to other systems in pursuit of a goal, with varying degrees of human oversight. The term covers everything from a scripted assistant that books a meeting to a research agent that gathers sources and drafts a report.
- AI chipsAI chips are processors designed or optimised to run machine learning workloads, especially the large matrix operations behind training and inference. The category covers GPUs, tensor and neural processing units, and custom ASICs, usually paired with high-bandwidth memory and fast interconnects. They are also called AI accelerators or AI semiconductors.
- AI cost managementAI cost management is the practice of tracking, forecasting and controlling what an organisation spends on AI systems, including model API calls, inference compute, vector storage and the tooling around them. It applies familiar financial discipline to usage that is variable, token based and easy to scale without noticing. The goal is predictable spend at an acceptable level of quality and latency, rather than the lowest possible bill.
- AI drug discoveryAI drug discovery is the use of machine learning and computational models to support the early stages of finding and refining new medicines. Models are applied to tasks such as predicting protein structures, identifying candidate molecules, prioritising targets and estimating properties like toxicity or binding affinity. The aim is to narrow a very large search space before expensive laboratory and clinical work begins.
- AI infrastructureAI infrastructure is the stack of hardware, networking, storage and software needed to train, fine-tune and serve AI models at scale. It spans accelerators such as GPUs, the data centres and power that house them, and the orchestration and serving layers that turn raw compute into working model endpoints. For most marketing teams it is a cost and capacity constraint they consume through APIs rather than something they build.
- AI procurementAI procurement is the process of evaluating, buying and contracting artificial intelligence tools and services, from assistants and content platforms to models accessed through an application programming interface. It covers commercial terms alongside security, data protection, accuracy and integration questions that do not arise with ordinary software. Most organisations run it as a structured review with pilots, stakeholder sign off and defined exit conditions.
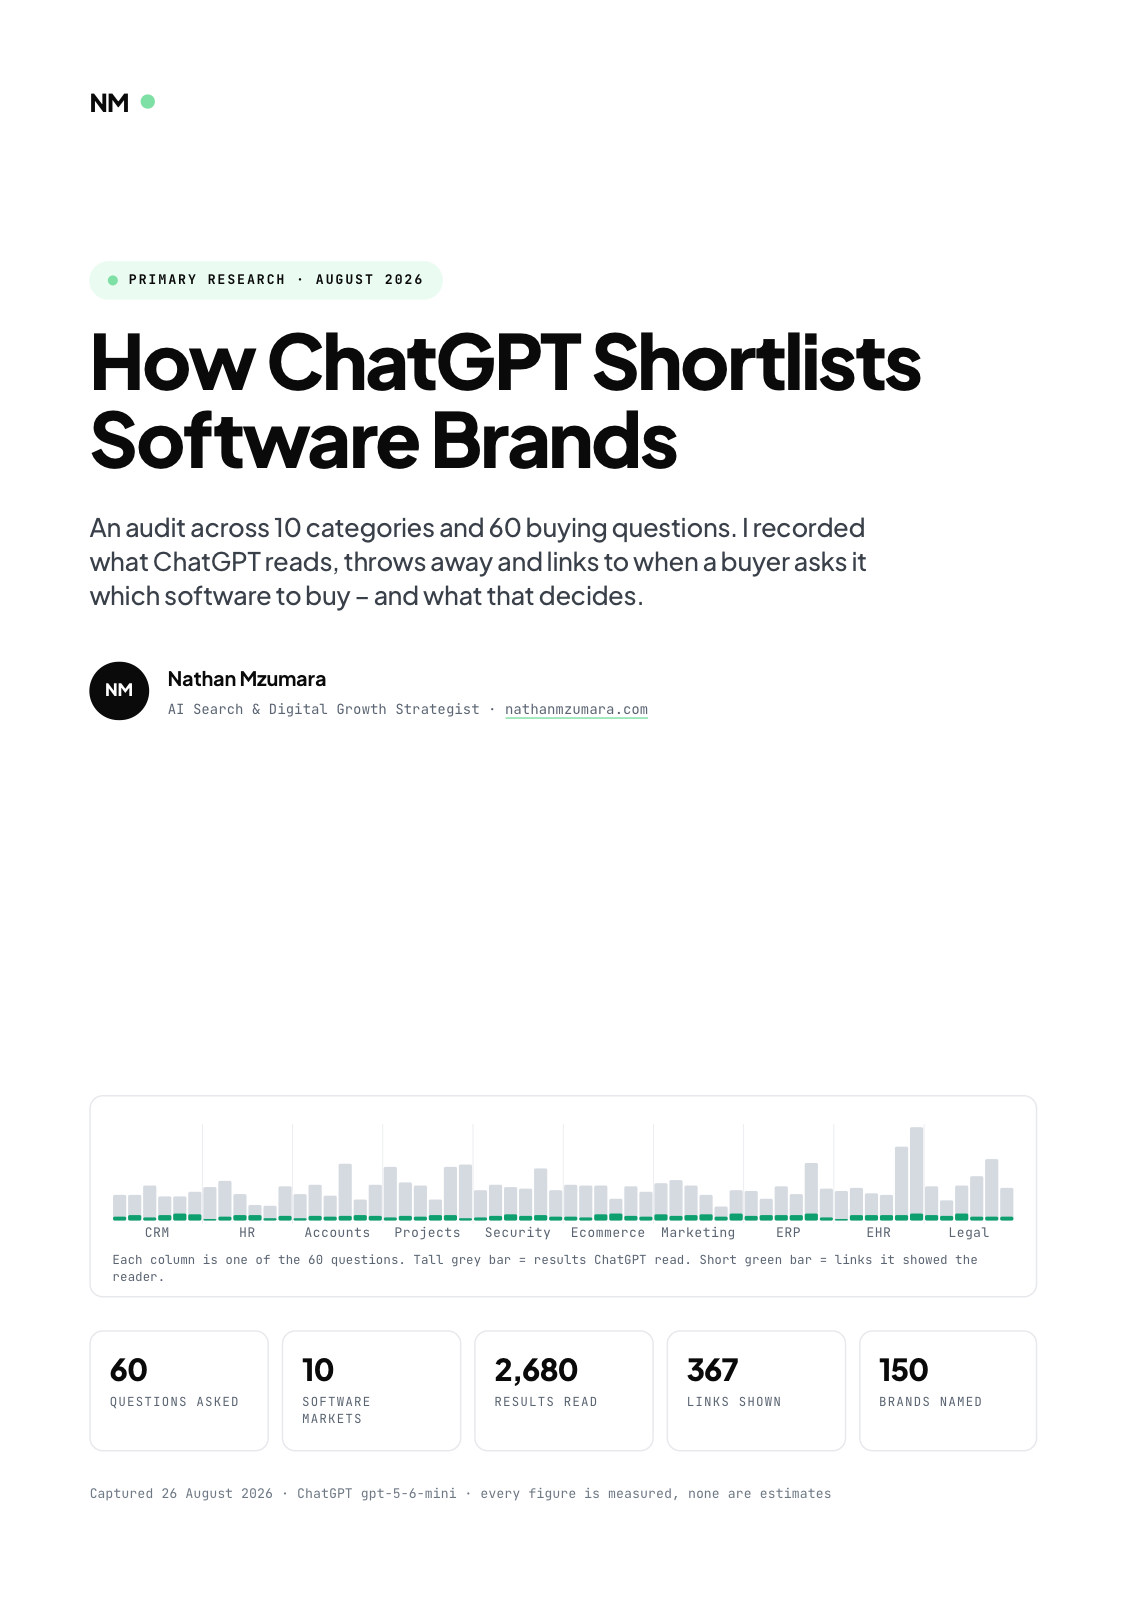
Primary research · August 2026
How ChatGPT Shortlists Software Brands
An audit across 10 categories and 60 buying questions. I recorded what ChatGPT reads, throws away and links to when a buyer asks it which software to buy, and what that decides.
- 60
- Questions asked
- 10
- Software markets
- 2,680
- Results read
- 367
- Links shown
Free download
Get the full report
35 pages · PDF · 536 KB. Enter your details and it downloads straight away.