AI Crawler
PerplexityBot
Perplexity's crawler. Allows real-time retrieval for Perplexity answers. Blocking reduces eligibility for Perplexity citation.
What it is
PerplexityBot is Perplexity's crawler that fetches and indexes pages so they can be retrieved in real time when answering user queries. It uses the PerplexityBot user-agent and is intended for retrieval rather than model training.
Why it matters
Perplexity surfaces explicit source citations, so eligibility for its index directly affects how often your domain appears as a cited source. Blocking PerplexityBot removes you from that citation pool.
How it works
Control access by naming the PerplexityBot user-agent in robots.txt with Allow or Disallow rules at site or path level. It is designed to honour robots.txt, so disallowing a path withholds it from Perplexity retrieval.
When it applies
Allow PerplexityBot when you want to be cited in Perplexity answers; block it for content you do not want surfaced as a real-time source.
Examples
- robots.txt: User-agent: PerplexityBot then Allow: / to enable citation eligibility
- robots.txt: User-agent: PerplexityBot then Disallow: /members/ to exclude gated content
- Server log shows PerplexityBot fetching a page within seconds of a related user query spike
How it is measured
- Crawl request count from the PerplexityBot user-agent per day
- Number of indexed URLs that subsequently appear as Perplexity citations
- Latency between content publication and first PerplexityBot fetch
- HTTP status codes served to PerplexityBot, monitoring blocked versus allowed paths
Related terms in AI Crawler
- ClaudeBotAnthropic's web crawler. Powers Claude's retrieval and training. Honour robots.txt; access controls are increasingly material to citation share.
- Google-ExtendedGoogle's opt-out signal for using your content in Bard, Gemini, and AI-powered Search features without affecting classical Search ranking. A separate lever from Googlebot.
- GPTBotOpenAI's web crawler. Used to gather training data and to power ChatGPT browsing. Can be allowed or disallowed in robots.txt; blocking may reduce ChatGPT citation eligibility.
- GrokbotGrokbot is the web crawler associated with xAI, the company behind the Grok assistant. It requests pages from public websites so that content can be used in xAI's products and model training. Site owners see it in server logs and can allow or restrict it through robots.txt and edge rules.
- OAI-SearchBotOpenAI's user-agent for ChatGPT Search retrieval (distinct from GPTBot, which is for training). Allowing this is required for inclusion in ChatGPT Search results.
- Web crawlingWeb crawling is the automated process of fetching pages and following links to discover and download content across a site or the wider web. Search engines, AI companies, SEO tools and archives all run crawlers to build indexes and datasets. Crawling is the discovery and retrieval step that happens before content is parsed, indexed or used to train or ground a model.
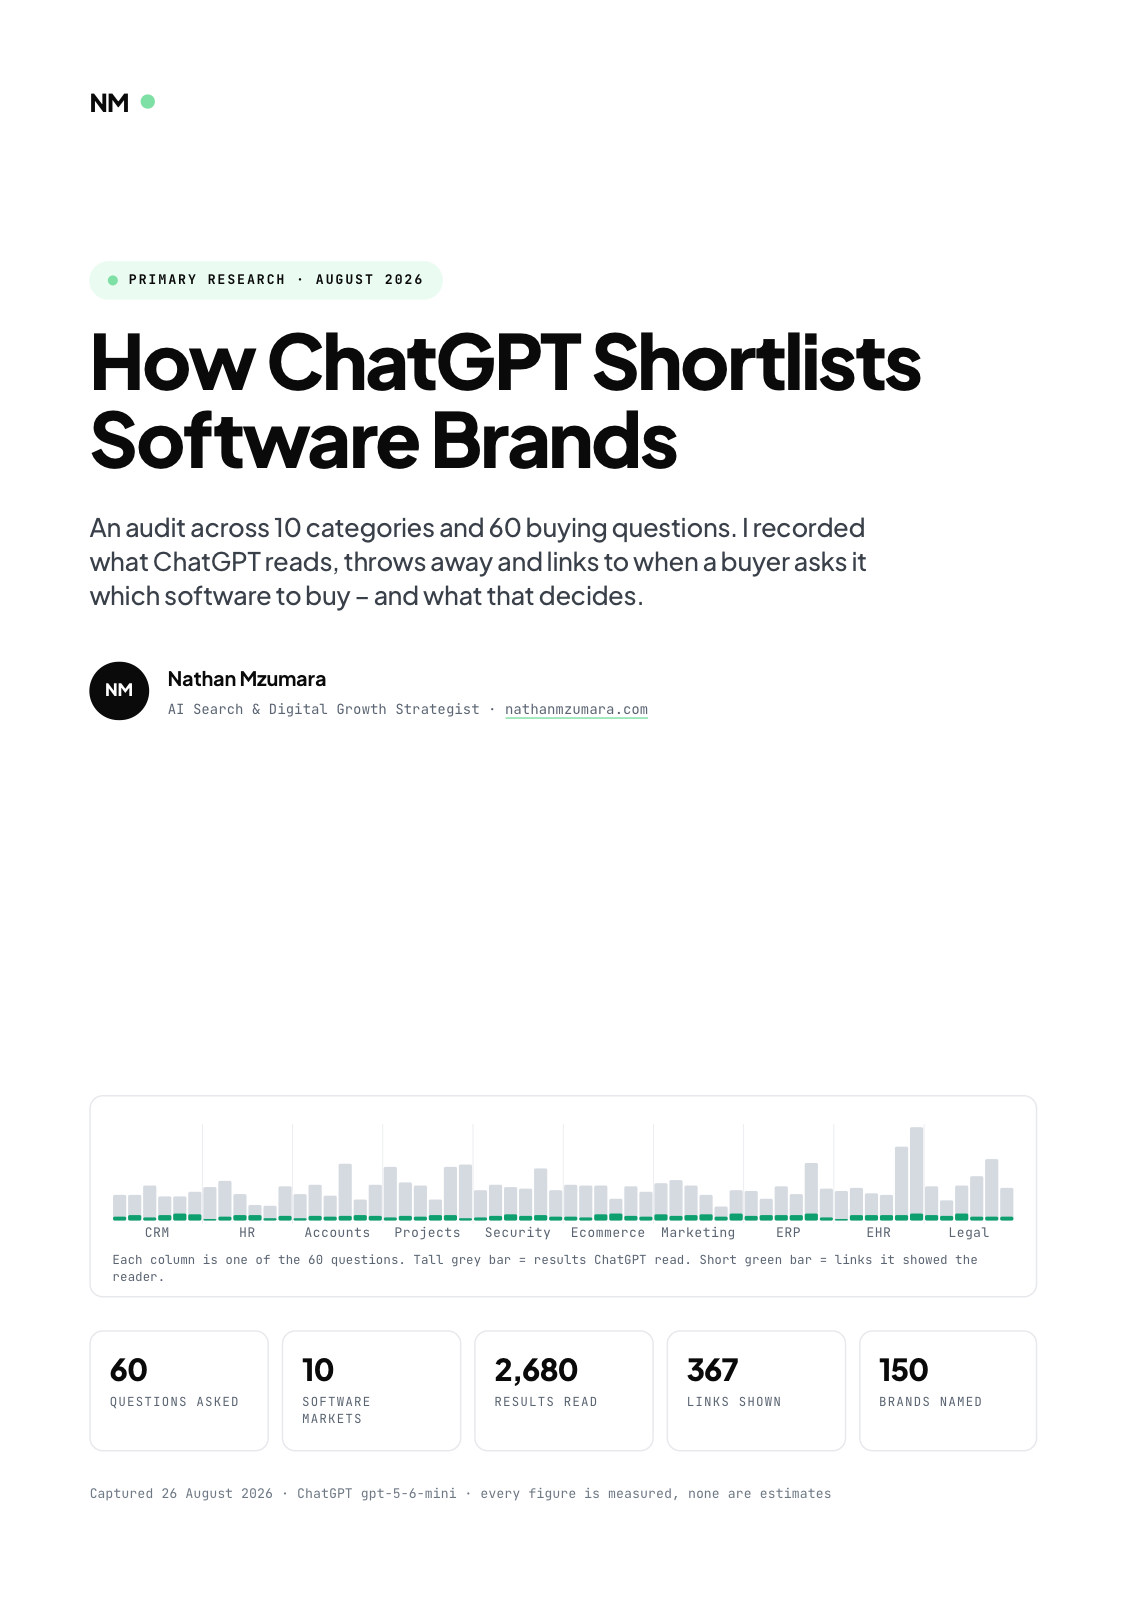
Primary research · August 2026
How ChatGPT Shortlists Software Brands
An audit across 10 categories and 60 buying questions. I recorded what ChatGPT reads, throws away and links to when a buyer asks it which software to buy, and what that decides.
- 60
- Questions asked
- 10
- Software markets
- 2,680
- Results read
- 367
- Links shown
Free download
Get the full report
35 pages · PDF · 536 KB. Enter your details and it downloads straight away.